2026-10-23
Canva launches Craft, its first in-house image model
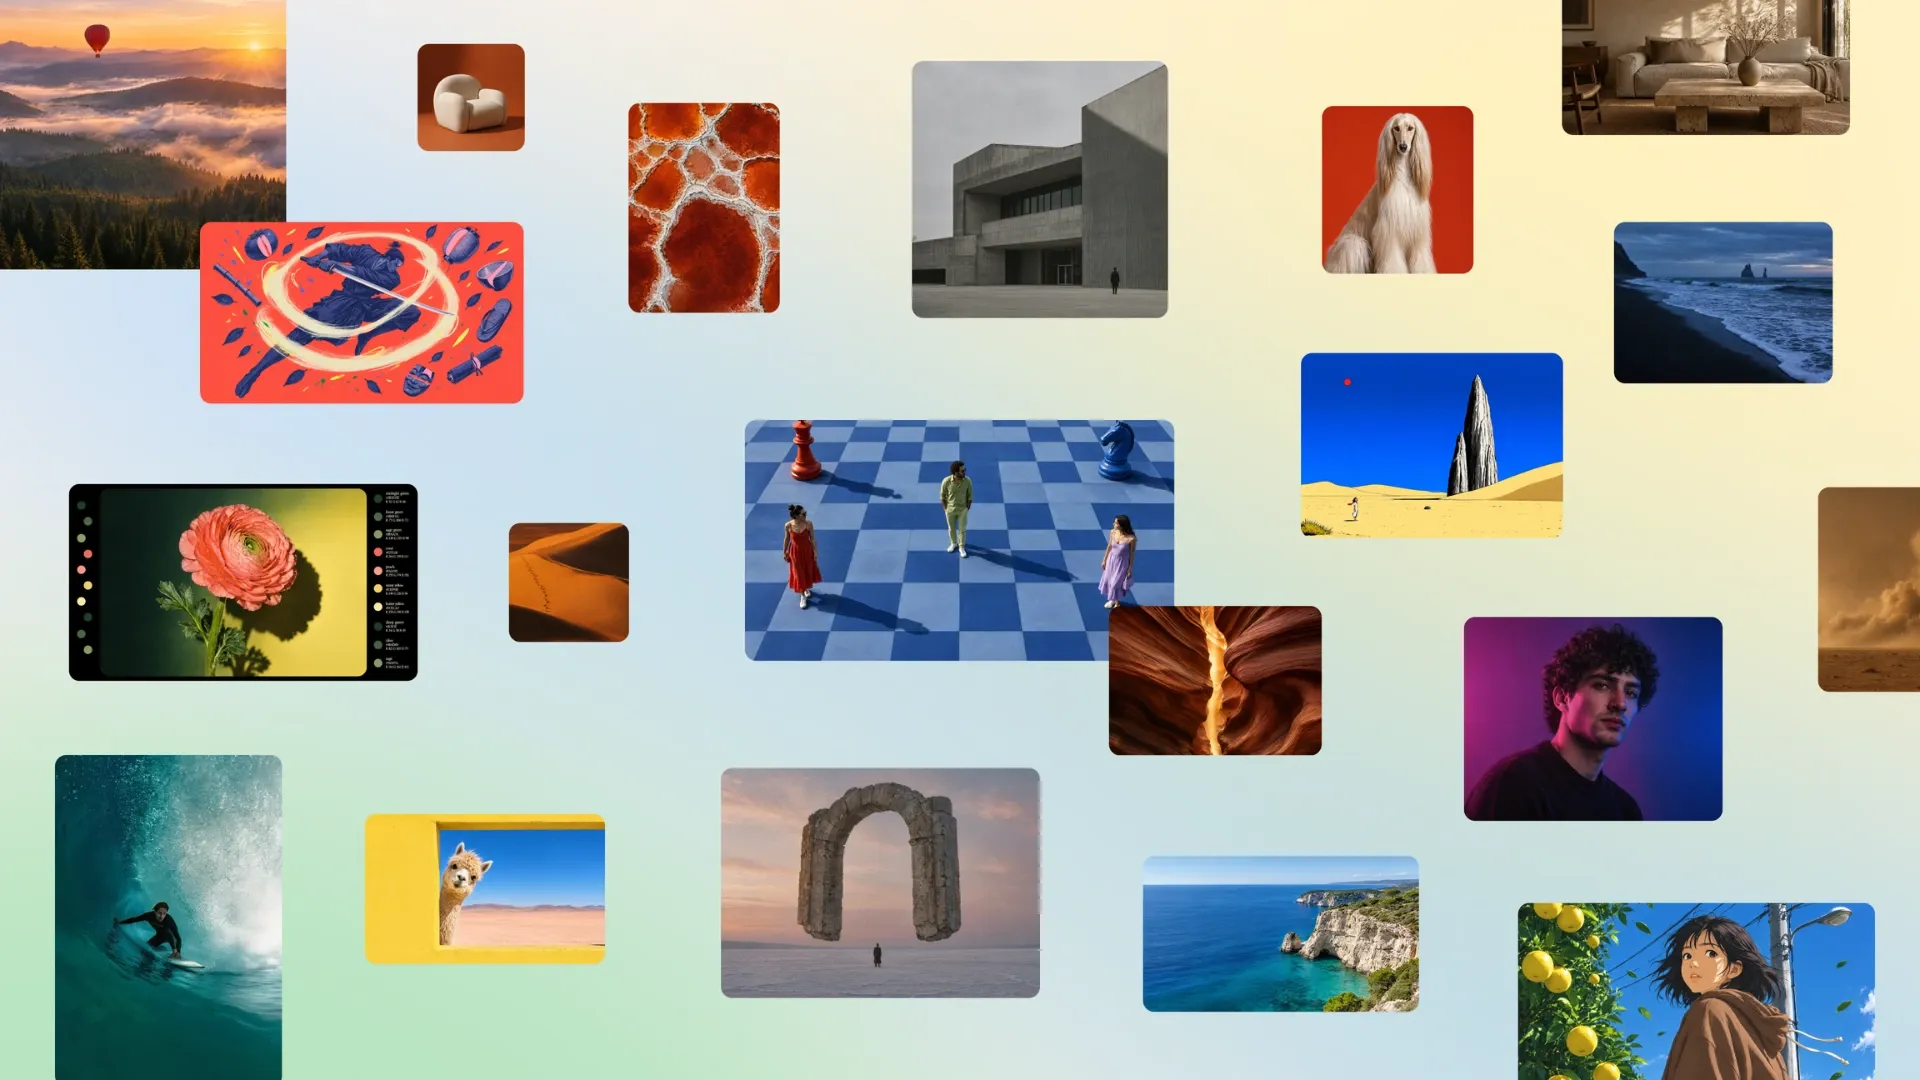
Design platform Canva has released Canva Craft, its first in-house image generation model
Homepage items are hidden so this list continues with earlier updates. Keep scrolling to load more.
Design platform Canva has released Canva Craft, its first in-house image generation model
Canva Craft generates 2K images with planned layouts, text in 55 languages and editable elements through Dream Lab and a public API.
Day-0 vLLM support for MiniMax-M3.1-Flash on NVIDIA Blackwell, NVIDIA Rubin, and AMD MI350-series GPUs, with NVFP4 MSA kernels, NVFP4 MegaMoE, DSpark speculative decoding
What's changed Fixed sandboxed Bash commands on macOS and Linux running the shell's startup files outside the sandbox before each command Fixed macOS sandbox denyWrite glob
What's changed Added /claude-api api-version to move Claude API code to API version 2026-10-21 Added the claude_code.safety_event OpenTelemetry event for each tool call a
In October 2026, French artificial intelligence lab Mistral released Voxtral 3, a family of native audio models capable of processing spoken voice across more…
Google Research has completed the 32-bit open-source Coral NPU RISC-V architecture with the introduction of its Matrix Execution Unit
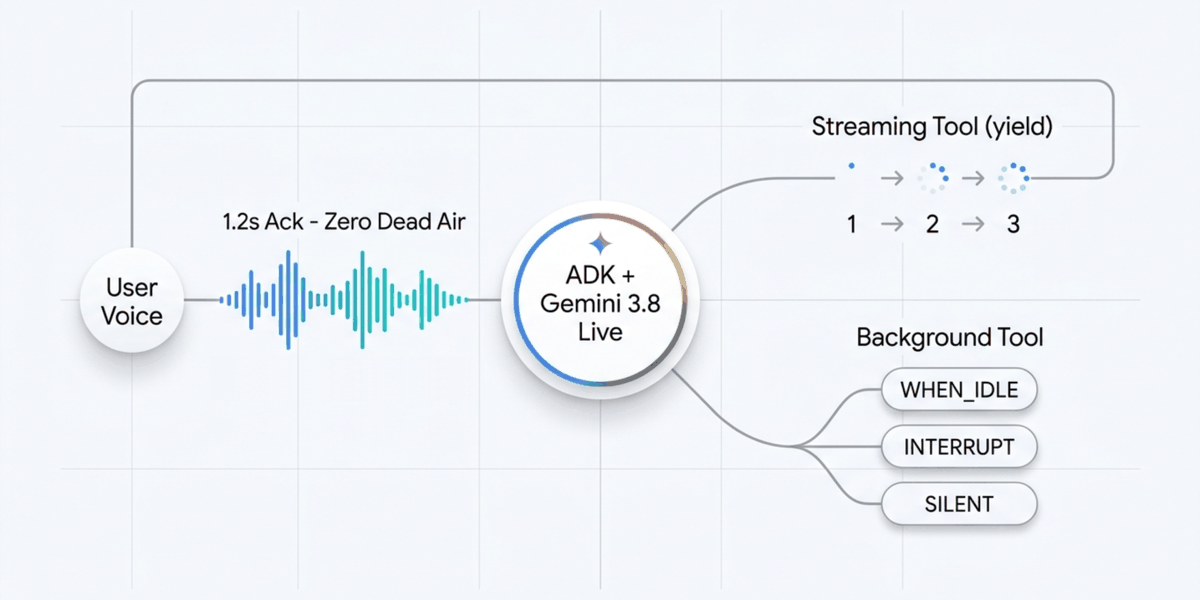
The open-source Agent Development Kit (ADK) and gemini-3.8-live enable developers to build responsive voice agents by implementing non-blocking tools in Python
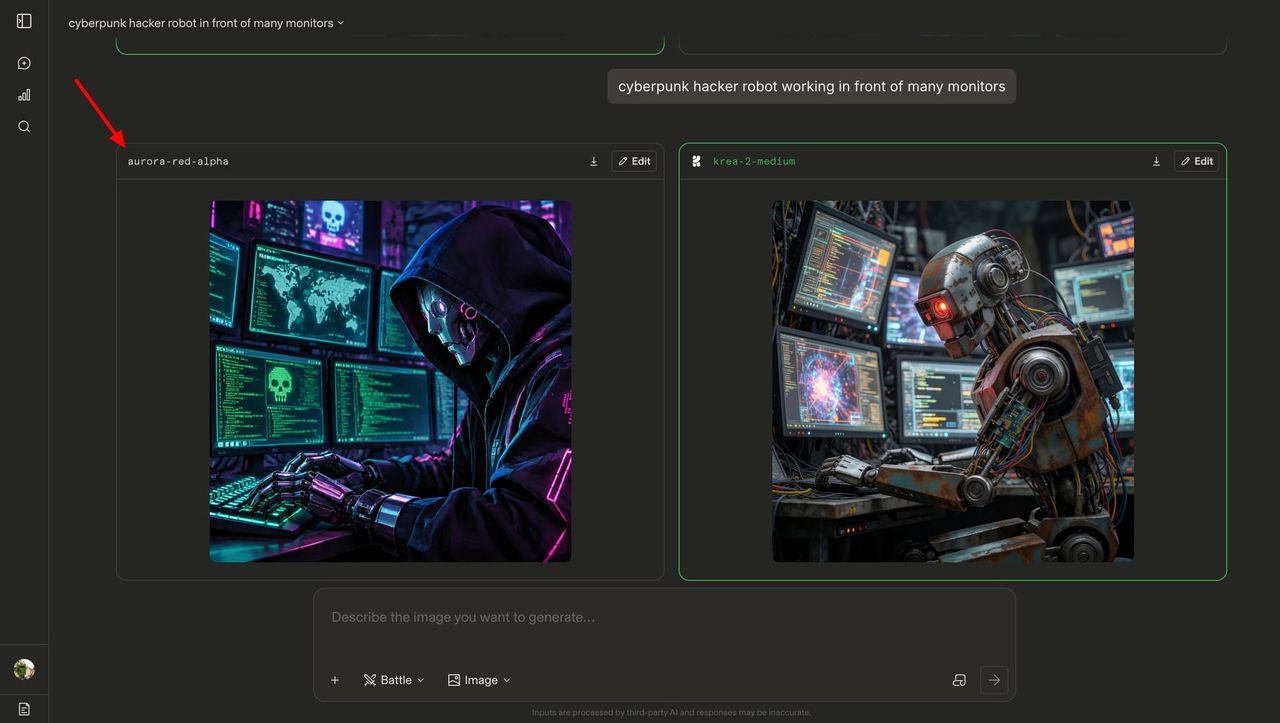
Three aurora alpha models briefly surfaced in OpenAI's API and are now in arena tests as image generators.
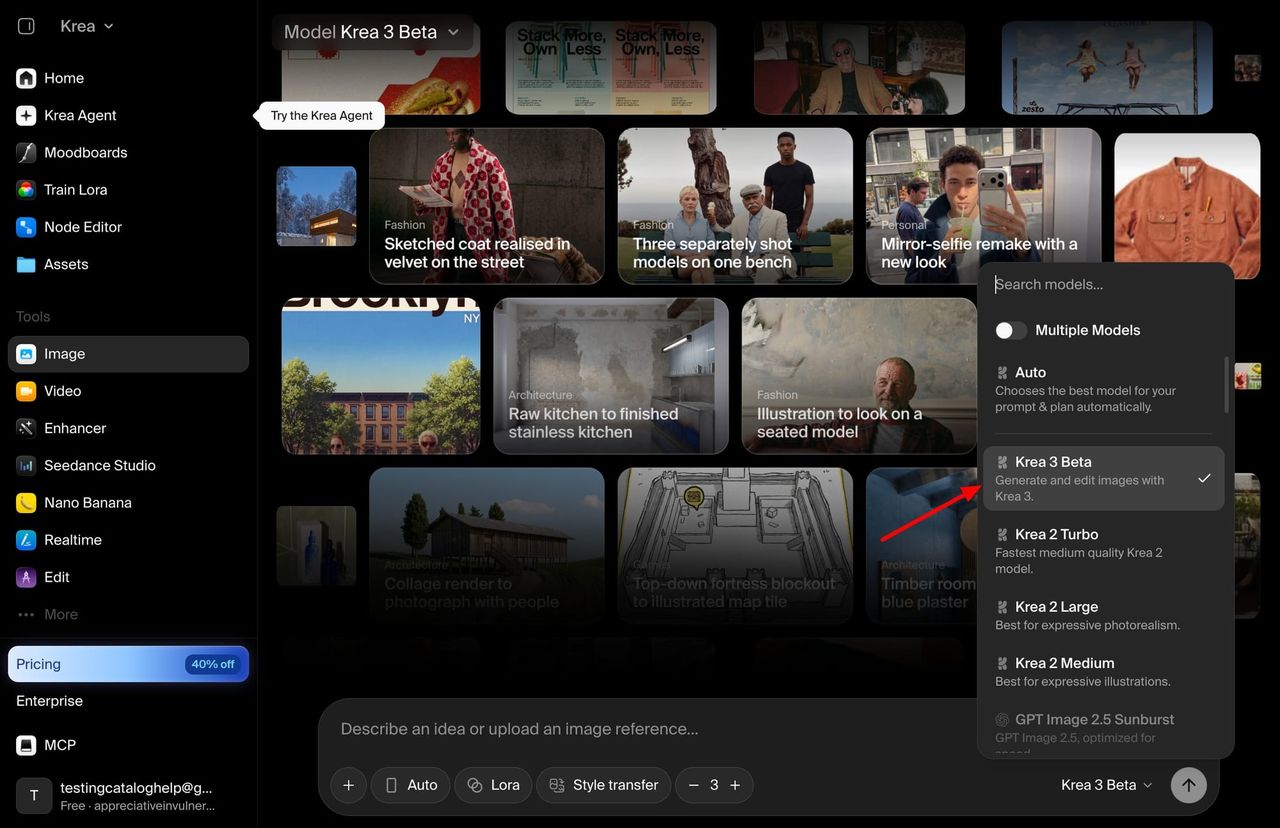
Krea says Krea 3 returns 2K edits in under 8 seconds and can be trained on a product, person or style. Pricing starts at $0.03 per image.
Run NVIDIA Nemotron 3.5 Super VL on vLLM for multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
Tool-augmented LLM agents discover relevant APIs from large registries before planning execution
Digital designers and content creators frequently generate high-resolution visual assets using AI image synthesis, only to upload them directly across social…
Open models like GLM-5 and MiniMax M2.7 now match closed frontier models on core agent tasks — file operations, tool use
GemPix 3 Pro references suggest Google is developing a Gemini 4 Argon-based image model that could become Nano Banana 3 Pro.
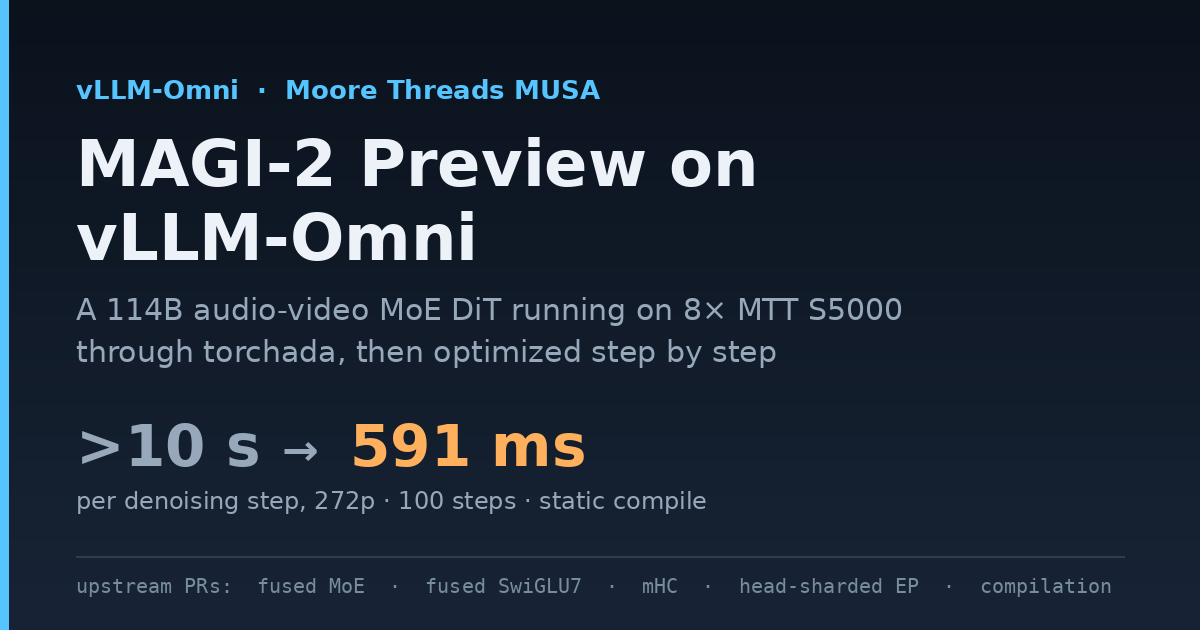
vLLM-Omni runs Sand AI's MAGI-2 Preview audio-video generation model on eight Moore Threads MTT S5000 GPUs through torchada's CUDA compatibility layer, then optimizes MoE, mHC
An internal Claude Voice preview suggests Anthropic is exploring a new interface, while its speech model plans and release timing remain unclear.
Generative image synthesis has evolved from experimental novelty into a foundational design utility.
Creators diving into generative AI video production frequently encounter a maddening, expensive financial trap: after loading a prompt box with poetic…
ElevenLabs is now on OpenRouter with 9 Text to Speech and 2 Speech to Text models
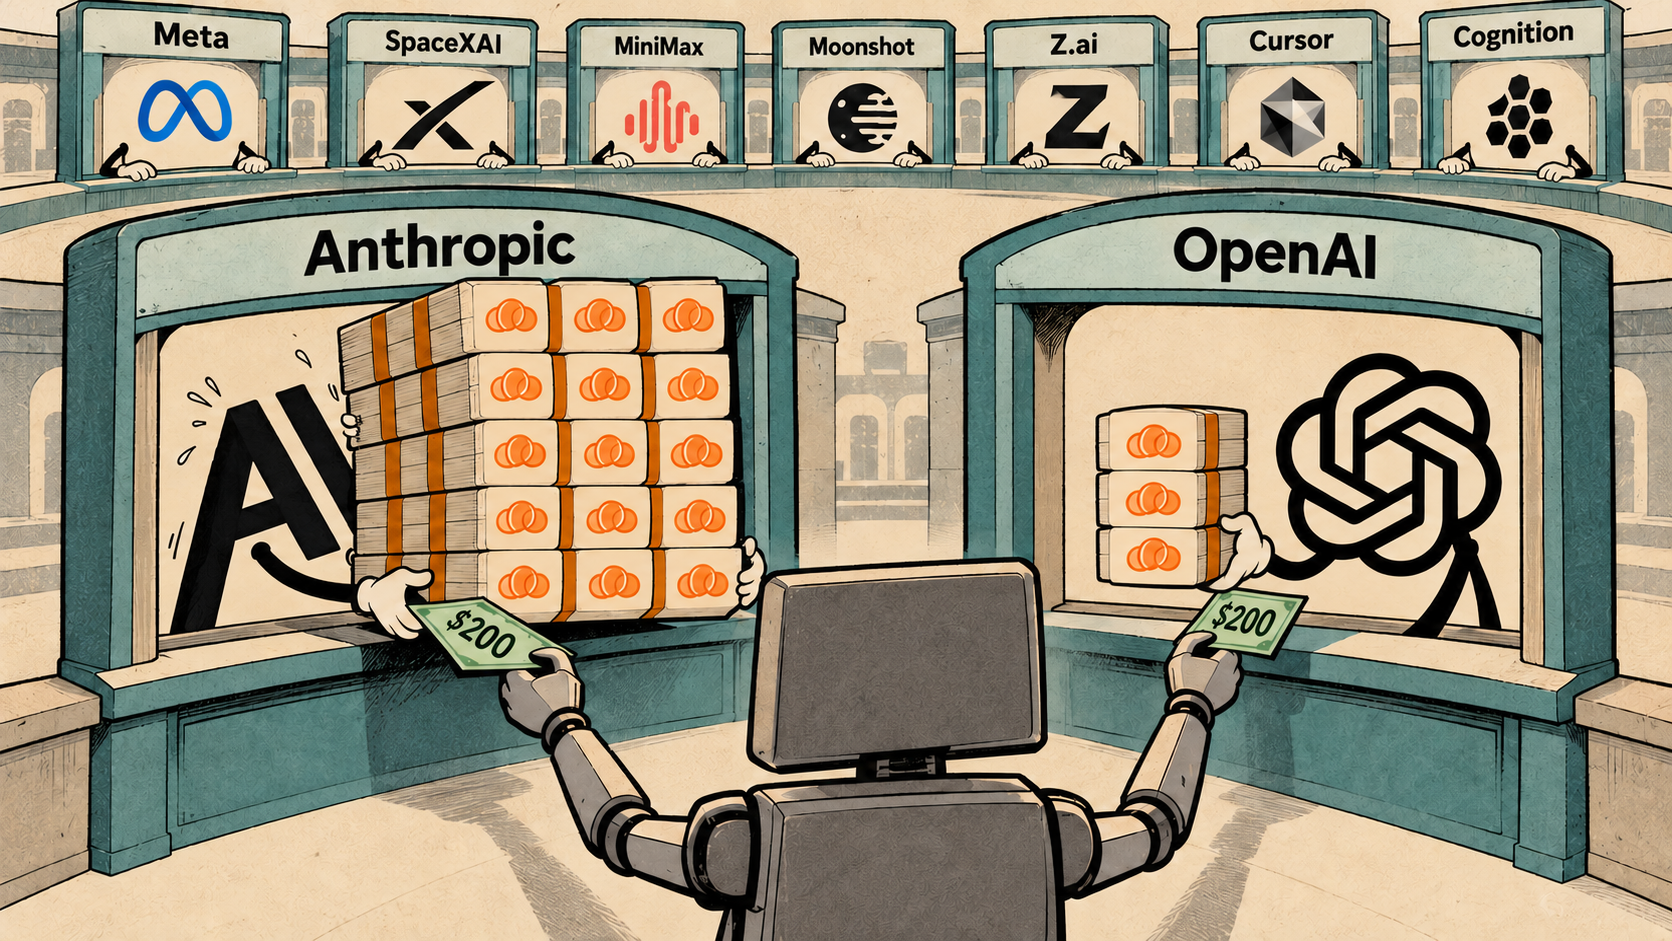
Limit testing every AI subscription plan from Anthropic, OpenAI, Meta, SpaceXSI, MiniMax, Moonshot, Z.ai, Cursor, and Cognition
A one-line prompt change can ship an agent that tells customers the wrong refund window, and nothing in a normal CI pipeline checks what the model says
Anthropic's Opus 5.5, released September 22, has spent the week being called the strongest video-generation model around, because it keeps producing things…
An agent's behavior can change when you edit a prompt, swap a model, change a tool schema, or change what retrieval returns
If you already have the image a video should start from, the model choice comes down to what has to happen after that frame
Suno released v5.5 on March 26 and called it its "most expressive model yet." The three new features are all about you: it can clone your singing voice,…